In statistics, the grouped Dirichlet distribution (GDD) is a multivariate generalization of the Dirichlet distribution It was first described by Ng et al. 2008.[1] The Grouped Dirichlet distribution arises in the analysis of categorical data where some observations could fall into any of a set of other 'crisp' category. For example, one may have a data set consisting of cases and controls under two different conditions. With complete data, the cross-classification of disease status forms a 2(case/control)-x-(condition/no-condition) table with cell probabilities
|
Treatment |
No Treatment
|
| Controls |
θ1 |
θ2
|
| Cases |
θ3 |
θ4
|
If, however, the data includes, say, non-respondents which are known to be controls or cases, then the cross-classification of disease status forms a 2-x-3 table. The probability of the last column is the sum of the probabilities of the first two columns in each row, e.g.
|
Treatment |
No Treatment |
Missing
|
| Controls |
θ1 |
θ2 |
θ1+θ2
|
| Cases |
θ3 |
θ4 |
θ3+θ4
|
The GDD allows the full estimation of the cell probabilities under such aggregation conditions.[1]
Probability Distribution
Consider the closed simplex set 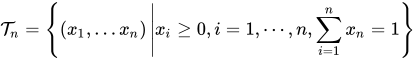 and
 . Writing
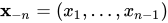 for the first
 elements of a member of
 , the distribution of
 for two partitions has a density function given by
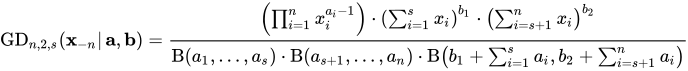
where  is the Multivariate beta function.
Ng et al.[1] went on to define an m partition grouped Dirichlet distribution with density of  given by
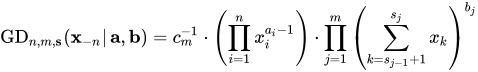
where 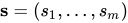 is a vector of integers with
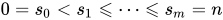 . The normalizing constant given by
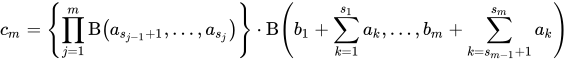
The authors went on to use these distributions in the context of three different applications in medical science.
References
- ^ a b c Ng, Kai Wang (2008). "Grouped Dirichlet distribution: A new tool for incomplete categorical data analysis". Journal of Multivariate Analysis. 99: 490–509.